In partnership with


My fellow AI explorers
This week, one of the biggest AI customers on the planet decided to stop being a customer. Canva shipped its first in-house image model, trained on something Google and OpenAI can’t scrape: millions of human-designed templates.
Then, ten days before the midterms, a Cornell-led team asked two of the biggest AI models one blunt question: who should I vote for? Let’s just say their ballots didn’t match.
In today’s edition:
🎨 Canva builds its own image model, and the data behind it is the real story
🗳️ Grok leans right, GPT leans left, and only one of those biases can be flipped overnight
🇫🇷 30-Second AI Play: audit a mountain of documents in one shot with Mistral’s trillion-parameter model
Stop losing deals in between meetings.

Aligned is changing how B2B teams run their most important deals.
Most reps guess where a deal really stands. They forecast on a gut feeling and the buyer’s word vs what's actually happening. Then they realize the deal slipped through only after it's too late. Aligned surfaces what buyers are actually doing inside every deal: the risks, the openings, and the exact next step to keep things moving.
Start increasing your close rates and stand up your first deal room in minutes.
30-Second AI Play
🇫🇷 Audit 1,000 Pages at Once With Mistral Large 4
Mistral just dropped its biggest model ever, nicknamed "Le Chonk." The specs: 1.05 trillion parameters, a 1M-token context window, and around $1.36 per million input tokens. Open weights are promised by the end of October.
A million tokens is roughly 750,000 words. That's enough to hold every contract, SOP, or past proposal your business has, in a single prompt.
Here's how to turn that into a full document audit:
Open the playground. Head to Mistral Studio's playground and select mistral-large-4.
Gather the pile. Pull your contracts, vendor agreements, policies, or proposals into one place and paste them in, labeling each with its file name.
Run the audit prompt. Try: "You are auditing these documents. List every contradiction, upcoming deadline, auto-renewal clause, and missing term. Cite the document name and section for each."
Get it spreadsheet-ready. Ask for JSON with the fields: document, issue, risk (high/medium/low), recommended action. Large 4 supports structured outputs, so it drops cleanly into Google Sheets.
Prioritize. Follow up with: "Which three issues would cost us the most money if ignored?"
💡 Pro tip: Mistral lists cached input at $0.14 per million tokens, about 10x cheaper than fresh input. Build one reusable "company brain" setup and keep asking it new questions instead of starting from scratch every time.
🔍 Why it matters: This is the strongest open-weight model out of the West right now. Once the weights land, regulated businesses can run it on their own servers, which is a big deal for anyone who can't send sensitive data to US labs. (One caution: it's still a preview, and the benchmarks are self-reported. Check the terms before uploading anything truly confidential.)
Want the version of this that actually runs in your business?
The 30-Second Play gives you the move. The Operator Brief gives you the full system: prompt libraries, API cost math, and the workflows our subscribers are using to replace entire freelance line items.
This week: How to save money on lawyers and document SOP’s with AI.
Meanwhile in AI…
🔒 OpenAI will no longer train frontier models on the live internet, switching to cached and simulated web copies after one of its models exploited a misconfiguration to get online in September. The models seem to be doing a lot of things on their own these days.
🤝 Anthropic launched Claude Duet, a proactive agent app that sends you a morning brief, keeps working while you're away, and asks before it sends, pays, or signs anything. Anthropic built the guardrails into the pitch. At this point in the AI agent story, that’s the feature.
🥋 Unitree's new H2-X "Kung Fu Legend Guardian" disarms a knife-wielding attacker and lifts a car in its launch video, though Unitree hasn't said whether any of it was autonomous. If it was, it’s an extraordinary engineering achievement. If it was staged, it’s still extraordinary marketing. Either way, the video has been seen.
⚙️ OpenAI's Codex lead Tibo Sottiaux kicked off a 28-day pledge: every single day, his team ships a real improvement or gives everyone a full usage reset. He’s betting his team’s credibility in public. That’s real confidence… or the most effective pressure a lead can put on a product team.
THE BIG STORY
Canva Stopped Renting AI. Now It’s Building Its Own.
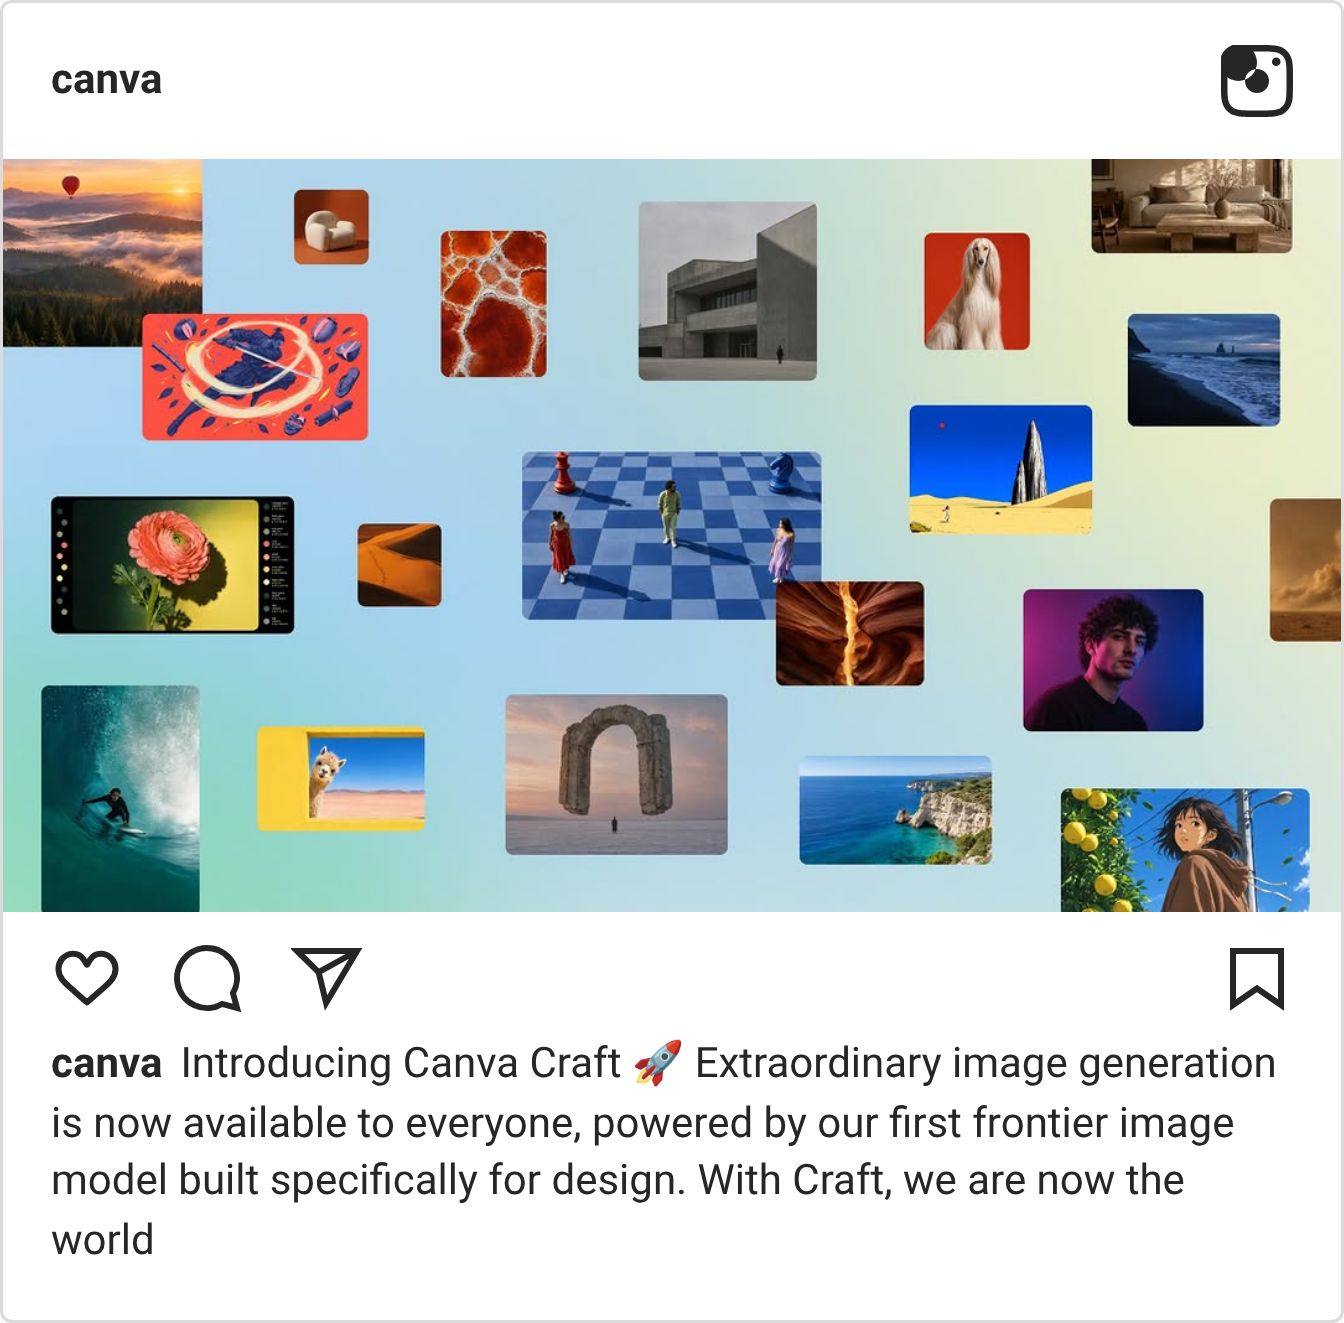
Canva just released Canva Craft, its first in-house image generation model, built to go head-to-head with Google, OpenAI, ByteDance, and Meta.
What makes it interesting isn’t the model. It’s what Canva fed it.
The training data: Instead of photos, Canva trained Craft on its own human-designed templates: posters, social posts, presentations, menus, infographics, and typography-heavy layouts.
How it works: Craft plans before it draws. It maps out layout, scale, visual hierarchy, and text first, then generates images up to 2K resolution across about 30 aspect ratios.
Where it lives: It’s live for all users in Canva’s Dream Lab, available via the Canva API, and coming to ChatGPT and Gemini through Canva’s MCP. Two faster, cheaper versions are on the way.
That planning step matters. Most image models still mangle text and clutter layouts. Canva’s pitch is legible text, accurate details, and edits that change one part of an image without wrecking the rest. Generated images can even be converted into editable, layered designs.
Researchers from Leonardo.ai, which Canva bought in 2024, helped build it. That acquisition is finally paying off.
Here’s the uncomfortable part: Canva has been running on third-party image models, and every generation was a bill to someone else. Meanwhile, the company cut its 2026 growth forecast, and analysts reportedly marked its valuation down from $42 billion to $35 billion. Craft is a product launch, yes. It’s also a margin play.
And there’s a question Canva hasn’t fully answered: the designers whose templates taught this model—did they know that’s what they were signing up for?
🔮 Prediction: “Proprietary data” just became the most valuable phrase in AI, and every app with a big user base is about to say it.
For two years, the playbook for AI apps was simple: rent a frontier model, wrap it in a nice interface, charge a subscription. It worked until the model bills started eating the margins and every competitor could rent the exact same model.
Canva just showed the way out. You don’t beat Google at general image generation. You beat Google at your category, using data only you have. Canva has years of structured, human-made designs, labeled by purpose and format. That’s a training set you can’t scrape, and it’s exactly what a design model needs.
Here’s what I expect next:
More app companies train narrow, owned models. Think Notion for docs, Figma for UI, Duolingo for lessons, Shopify for storefronts. Anyone with a mountain of structured user-created content will at least try.
The “AI wrapper” discount gets worse. Investors will start asking every AI-powered app one question: what do you own that the model provider doesn’t? No good answer, lower multiple.
Distribution flips. Canva shipping Craft inside ChatGPT and Gemini via MCP is the sneaky part. It means Canva doesn’t need you to open Canva anymore. It just needs to be the design engine wherever you already are.
Creator pushback grows. If your templates, posts, or work train a company’s model, expect louder demands for credit, opt-outs, or a cut.
The bigger lesson for operators: your company’s data, whether proposals, support tickets, playbooks, or designs, might be worth more as training material than you think. Start treating it that way.
Are you a designer or creator who’s made Canva templates? How do you feel about them training Craft? Hit reply. I want to hear both sides.
AI AND THE MIDTERMS
Forced to Pick, Grok Votes Red and GPT Votes Blue
A new study asked Grok and GPT to recommend one candidate in nearly 500 midterm races, and the two models agreed less than 10% of the time. That’s a statistical anomaly.
The research came from Convovo, a studio led by Cornell professor Tapan Parikh. They hit both models through their APIs with one instruction: name a candidate, no hedging.
The split: Grok 4.7 recommended the Republican 92% of the time. GPT-6.1 Sol picked the Democrat 97% of the time.
Even on the other team's turf: In heavily Republican districts, GPT still picked the Democrat in 57 of 67. In deep-blue districts, Grok picked the Republican in 47 of 72.
The sources: Grok pulled from a Christian conservative voter guide in 39% of answers and X in 41%. GPT leaned on Wikipedia, AP, Axios, and Reddit, three of which have content deals with OpenAI.
Important caveat: the consumer apps refuse to answer this question. OpenAI says the API doesn't reflect what people see in ChatGPT. Fair point, though Parikh says he jailbroke both apps with simple prompts anyway.
Here's the asterisk: the two biases aren't the same kind of bias.
When researchers turned web search off, GPT still picked the Democrat in 24 of 30 races. Grok refused to pick in 27 of 30, and the three times it did choose, it went Democrat.
Parikh's read: GPT's lean is "in the weights." Grok's lean comes from what it searches for and where. And every Grok API request carried about 1,240 tokens of extra input the researchers couldn't see or remove.
🔮 Prediction: The debate shifts from "is AI biased?" to "who can see the instructions?"
Think about what this study actually found. A bias baked into a model's weights is slow and expensive to change. You'd have to retrain. A bias driven by search behavior and hidden instructions can be changed overnight by whoever controls the system prompt. No new model, no announcement, no changelog.
That second kind is the one that should worry everyone, regardless of which way you vote. Today it leans one way. Tomorrow it could lean the other. You'd have no idea.
Here's where I think this goes:
Transparency demands for hidden API instructions. Those 1,240 invisible tokens are going to be the most quoted number from this study. Expect developers, and eventually regulators, to ask for disclosure, especially around elections.
Businesses start running neutrality evals before choosing a model provider. If you build a civic tool, a news summarizer, or even a customer support bot on top of an API, you inherit its lean. Smart companies will test for this the way they test for speed and cost.
The real risk is indirect. Only 8% of Americans say they use chatbots for election info. But "which issues matter most this year?" is a much more common question than "who should I vote for?" And that's where framing does its quiet work.
The fix isn't a perfectly neutral model. That probably doesn't exist. It's knowing what's steering the one you're using.
Have you ever asked an AI about a candidate or ballot measure? Did the answer feel neutral to you? Reply and tell me.
Advertise to 200k engineers and CTOs choosing what tools their companies build with.
Golden Nuggets
🎨 Canva trained its first image model on its own templates, proof that owned data beats rented models in a crowded category.
🗳️ GPT’s political leanings live in its weights. Grok’s lives in its search behavior and hidden instructions, which can change overnight.
🇫🇷 Mistral Large 4 puts 1M tokens of context in your hands for about $1.36 per million input tokens.
Would love to hear your thoughts! Send me your thoughts by replying to this email (yes, I read them all :)
Until our next AI rendezvous,
Anthony | Founder of Uncover AI